Experiments
A/B test pricing without rolling your own infra.
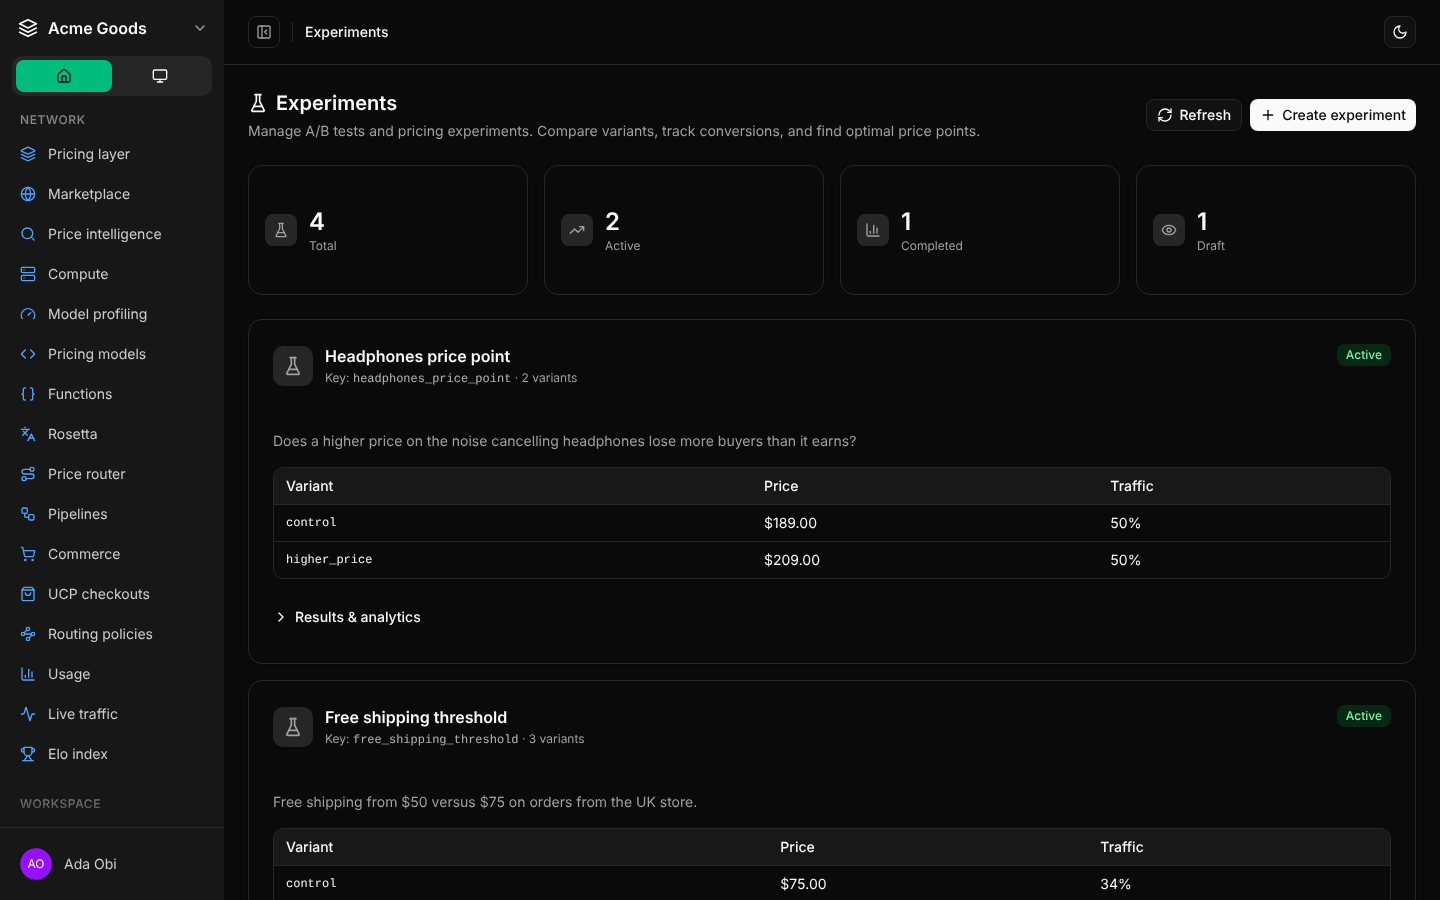
Run up to ten prices against each other, one of them your control. Each user gets a stable arm, you report conversions, and the results test every arm against control for statistical significance on views, conversions, revenue and revenue per user.
What you can do
- Test from two to ten arms, one named control, each with its own price.
- Assign users with a stable hash. Same user, same arm, every call, from the pricing API or the Elo A/B test built-in.
- Track conversion and revenue per arm against statistical significance: every arm is tested against control, with the bar raised for each extra arm so more arms do not mean more false winners.
- Split traffic evenly or by weight, or let bandit allocation set the next weights from the evidence so far with POST /api/compute/allocation.
- Report conversions with revenue from your server, or from your page with an embed token.
Create an experiment
POST /api/tenants/{tenantId}/experiments
x-api-key: lp_...

{
  "key": "checkout_v3",
  "name": "Checkout price test",
  "variants": [
    { "name": "control",    "price": 29.99, "weight": 40 },
    { "name": "experiment", "price": 24.99, "weight": 30 },
    { "name": "premium",    "price": 34.99, "weight": 30 }
  ]
}
Get a user's price
GET /api/experiments/checkout_v3/pricing?userId=u_8821
x-api-key: lp_...
{
  "userId": "u_8821",
  "experimentId": "checkout_v3",
  "variant": "experiment",
  "pricing": { "plan": "Experiment", "price": 24.99, "features": [...] }
}
GET /api/me returns the tenantId your key belongs to. Report a sale with POST /api/experiments/checkout_v3/convert, and read every arm with GET /api/experiments/checkout_v3/results, which also compares each one with control.
Experiments take 2 to 10 arms, one of them control, assign each user a stable arm by hash, record each arm's views, conversions and revenue, and test every arm against control for statistical significance, with bandit allocation to split the next traffic; the Elo A/B test built-in function assigns arms by the same hash inside a compute call.
Recent changes
All Experiments notes- New
Your agent can pause, delete and correct experiments
Three new MCP tools, set_experiment_status, delete_experiment and remove_experiment_conversions, let ChatGPT, Claude or any agent start, pause or complete an experiment, delete one, and take out wrong conversions.
- New
Know when an experiment can stop, and let traffic follow the winner
Experiments can now tell you when it is safe to stop, with a verdict that stays valid however often you check, and can shift traffic toward the arms most likely to win, with every change recorded.
- New
Pause experiments and correct their conversions
Start, pause or complete an experiment, remove a wrong conversion, and limit an embed token to the experiments one page runs.
- New
Manage pricing controls and experiments over MCP
Compute batches, configure routing and guardrails, and manage price experiments from an MCP client.
- New
Price experiments with up to ten arms
An experiment can now test up to ten prices at once instead of two, and its results compare every arm with your control, raising the bar as you add arms so more arms do not mean more false winners.
Ready to try it?
Spin up a free playground tenant in under a minute. No credit card.